Crashes and timeouts
Trace logs, exceptions and infrastructure signals to identify failing requests, resource pressure and recurring errors. Establish the incident scope and customer impact.

Services for existing applications
Recurring crashes, stalled jobs and broken integrations can make every release feel risky. We diagnose the immediate failure, restore dependable processing and leave a recovery plan your team can use.
Trace logs, exceptions and infrastructure signals to identify failing requests, resource pressure and recurring errors. Establish the incident scope and customer impact.
Inspect queue state, retries, external API failures and webhook processing. Check duplicate-processing and data consistency risks before retrying or replaying work.
Review release steps, configuration, migrations and rollback options. Identify the changes that make production fail and the access needed to recover safely.
Document the likely root cause, affected workflows and immediate options. Agree the safest recovery steps, responsibilities and communication cadence.
Implement the agreed fixes, restore processing and verify critical workflows. Make retries and recovery explicit so a restart does not conceal the underlying problem.
Add targeted tests, monitoring and error handling. Separate immediate fixes from the larger upgrade, refactoring or infrastructure backlog.
We agree access, availability and response arrangements before starting. Start by describing the affected workflow, when failures began and the logs or monitoring available. The initial discussion establishes whether the required incident coverage fits our capacity.
Receive the diagnosis, changes delivered, checks performed and any unresolved risks. Compare the affected workflow before and after the fix using request errors, queue progress or integration consistency. Agree an observation period and document what the evidence does and does not establish.
Document operational checks, escalation contacts, rollback and replay steps, plus a prioritized follow-up backlog. Agree ongoing maintenance separately when the application is stable.
Documented client work
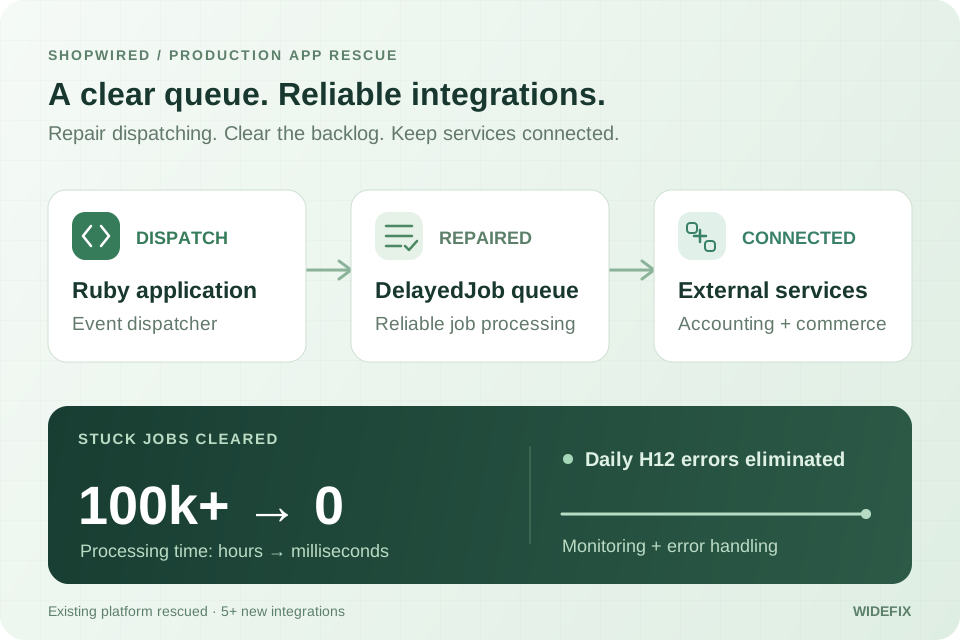
Analyzed and redesigned DelayedJob handling and dispatching, unblocked the completely stalled queue and eliminated H12 errors that had occurred multiple times per day. Added monitoring and error handling.
Read the case studyTook ownership during a developer handover, repaired existing defects and added automated tests while continuing product delivery.
Read the case studyExplore the next step
Explore focused services for your application and the technical experience behind our work.
Related service
Investigate slow requests, queries, queues and memory usage with a measured audit and prioritized fixes.
Explore the serviceRelated service
Plan incremental dependency upgrades and modernization while maintaining the working application.
Explore the serviceRelated service
Keep production support, dependency updates and continued feature development in one prioritized backlog.
Explore the serviceEngineering article
Read our Ruby and Rails upgrade experience, including compatibility fixes and background job loading issues.
Read the engineering articleTell us about your application, the current problem and your priorities. We will agree on the scope, access needed and a practical first step.
